I build production AI systems where the model is the product.
AI/ML engineer with 4+ years shipping LLM systems to real users: a speech-AI service for a US telephony provider, the multi-agent engine that lets a 12B model do 32B-class work, and RAG over 10M+ embeddings, often on-prem and air-gapped.
Production speech AI for a US hosted-telephony provider's voicemail and call-recording features.
Speech AI · in production
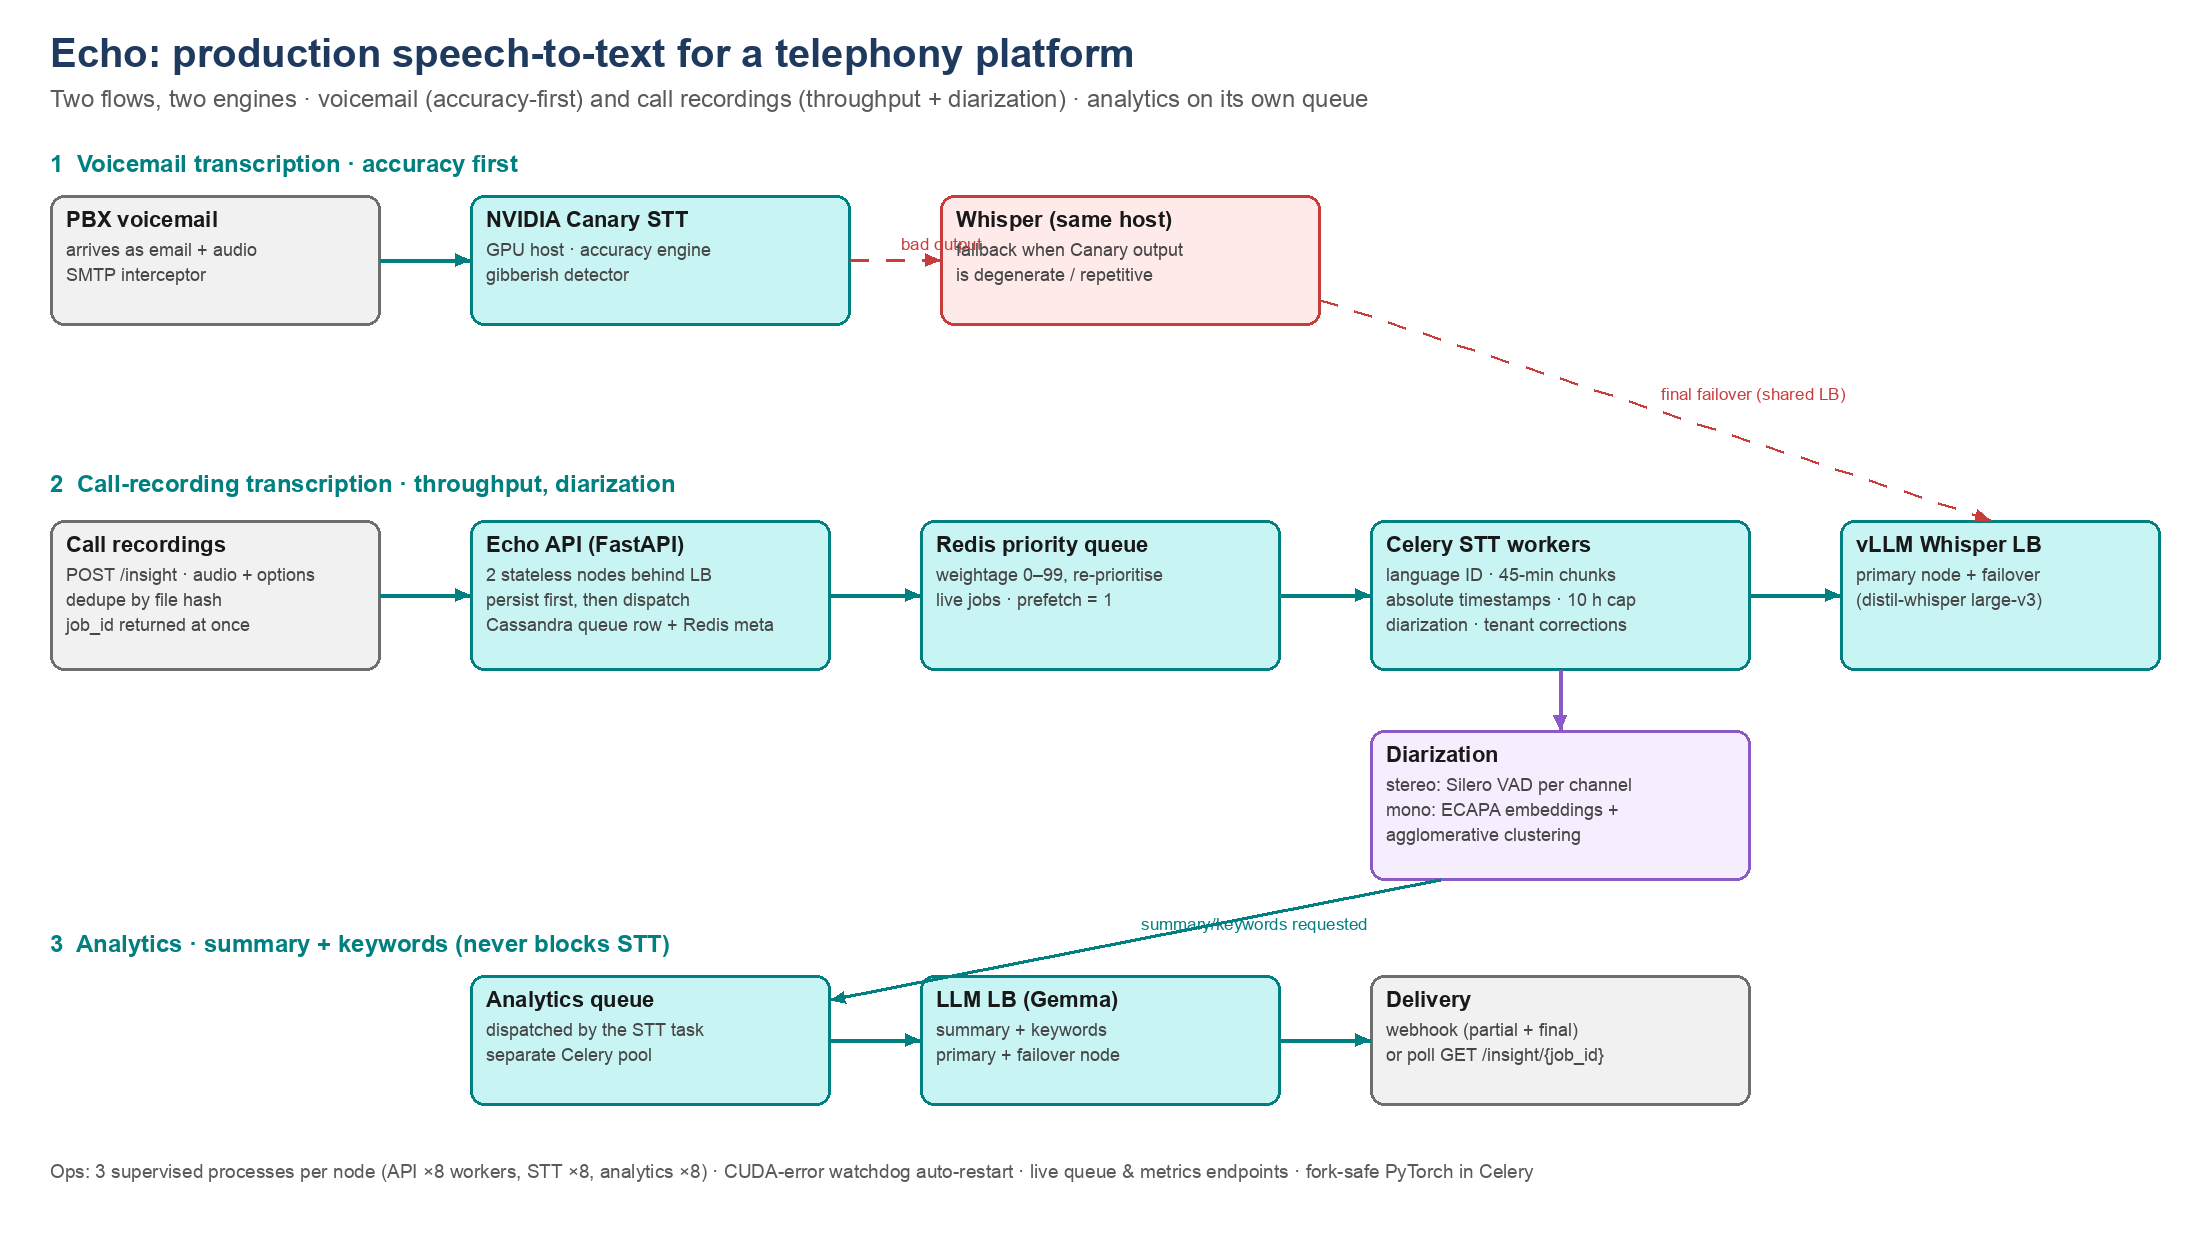
Two flows, two engines, one reliable service
Voicemail, accuracy-first: NVIDIA Canary, with automatic fallback to Whisper when output is degenerate, and a final failover to the shared vLLM tier.
Call recordings, throughput-first: Whisper served on vLLM behind a load balancer, Redis priority queues (0–99) with live re-prioritisation, and Celery workers on stateless HA nodes.
Long audio: 45-minute chunks up to 10 hours, with timestamps kept absolute across chunks; automatic language ID.
Speaker diarization: Silero VAD per channel for stereo; ECAPA-TDNN embeddings with agglomerative clustering for mono.
LLM analytics that never block transcription: Gemma summaries and keywords on a separate queue and load balancer, delivered by webhook or polling.
Echo architecture (host and customer names omitted)
Selected work
Everything here runs in production or is public on GitHub.
Agents
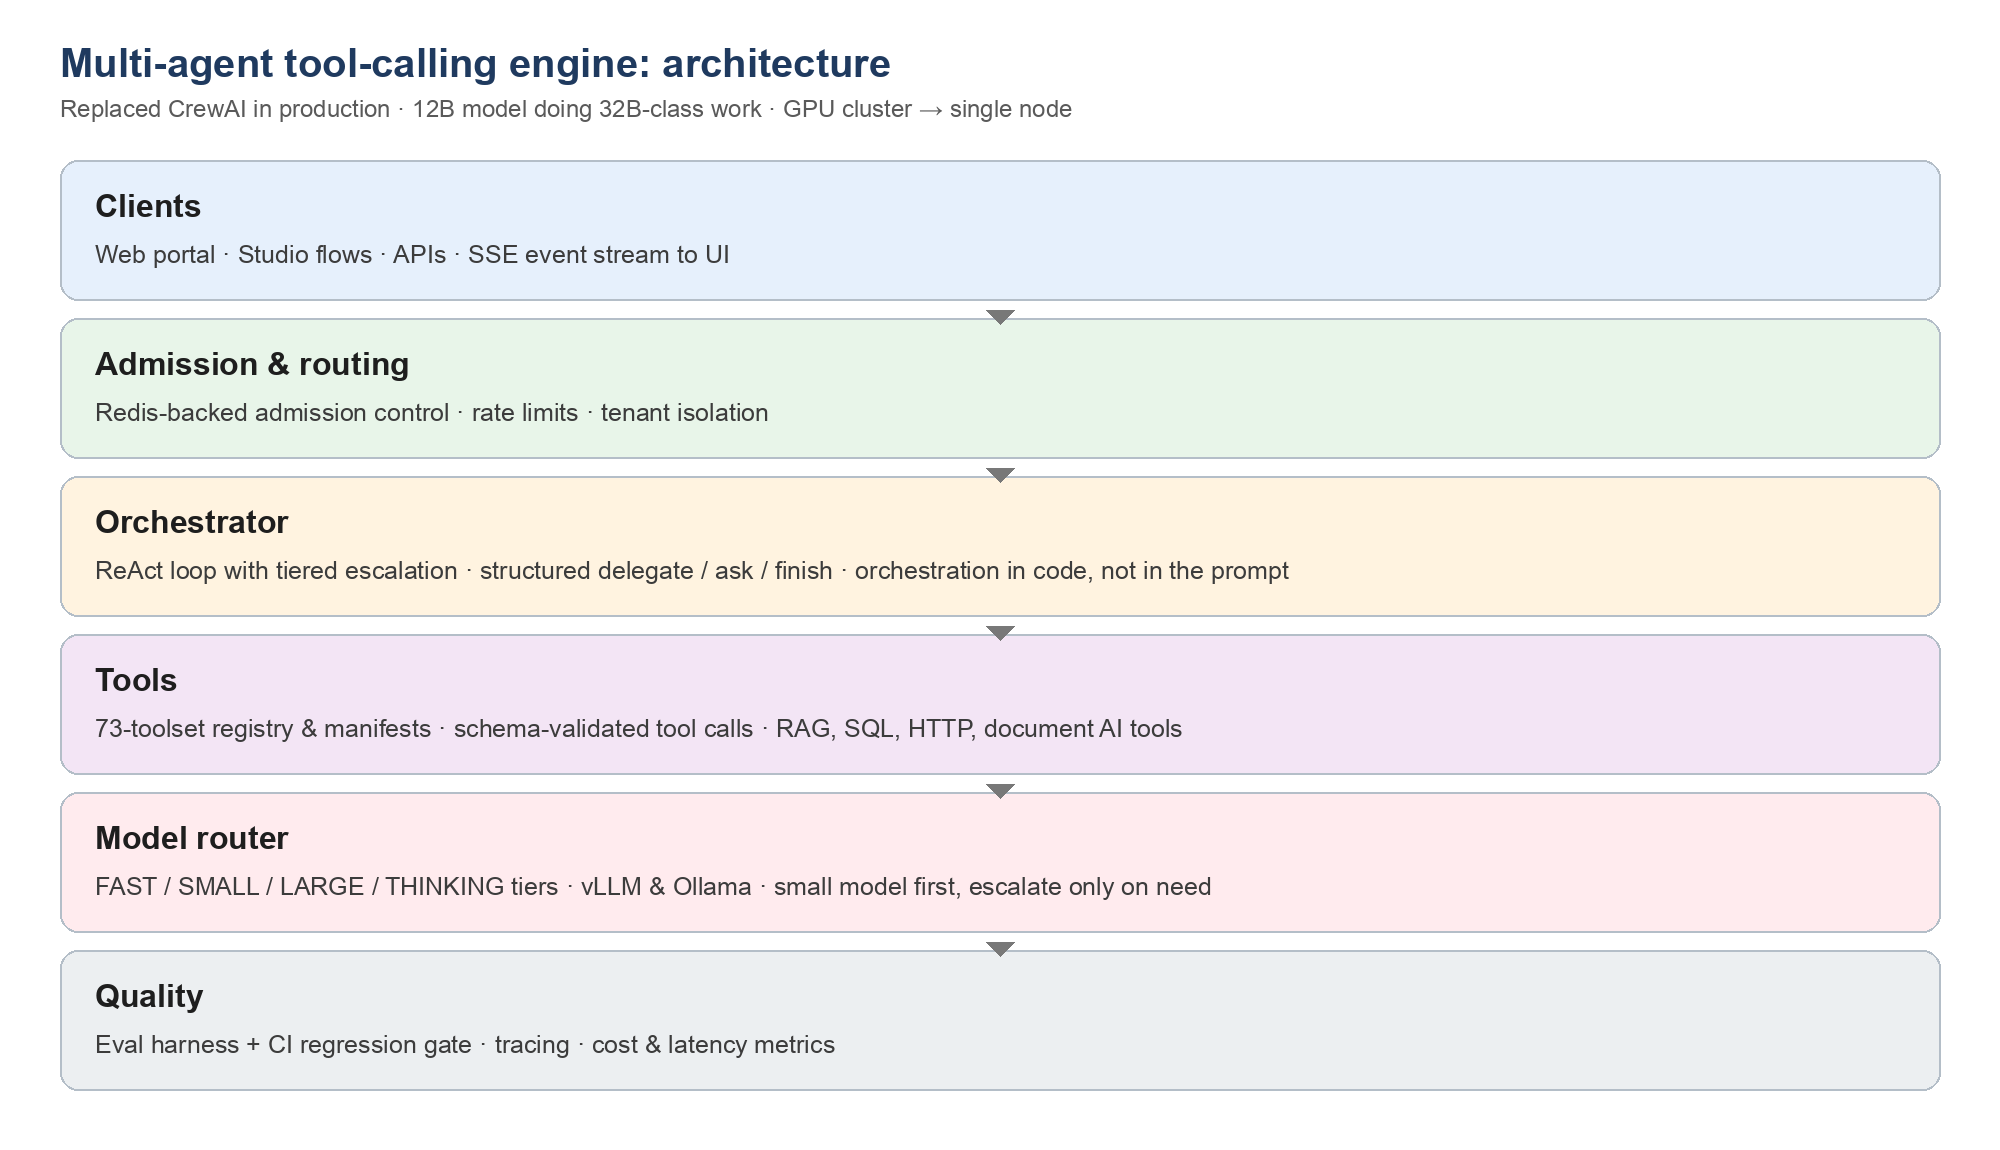
Multi-agent tool-calling engine
Replaced CrewAI · 12B model doing 32B-class work · GPU cluster → single node
I wrote the engine behind an enterprise on-prem LLM platform (~49k lines, largest contributor): a 73-toolset registry with schema-validated tool calls, ReAct with tiered escalation, structured delegate / ask / finish steps, a FAST/SMALL/LARGE/THINKING model router over vLLM and Ollama, SSE event streaming and Redis-backed admission control.
Ingestion with Docling for layout-aware parsing (PDFs, DOCX, tables, figures) and RapidOCR / PaddleOCR-VL / Qwen-VL for scanned documents; structure-aware chunking; hybrid dense + keyword retrieval with re-ranking. Runs on Cassandra Vector, pgvector, Qdrant and FAISS across 8 Kubernetes environments, built to HIPAA-style controls.
Whisper speech-to-text and Tacotron2 text-to-speech shipped into a video-calling product. Document AI with PaddleOCR-VL and Qwen-VL served via Transformers, LayoutLMv3 fine-tuning and multiple OCR engines feeding the RAG pipeline.
LoRA / QLoRA fine-tuning of open models for Arabic with Unsloth and PEFT, plus Arabic-aware retrieval (normalisation and hybrid search). I am proficient in reading and understanding Arabic, which helps when checking model output for Gulf products.
UnslothLoRAPEFTHugging Face
Automation
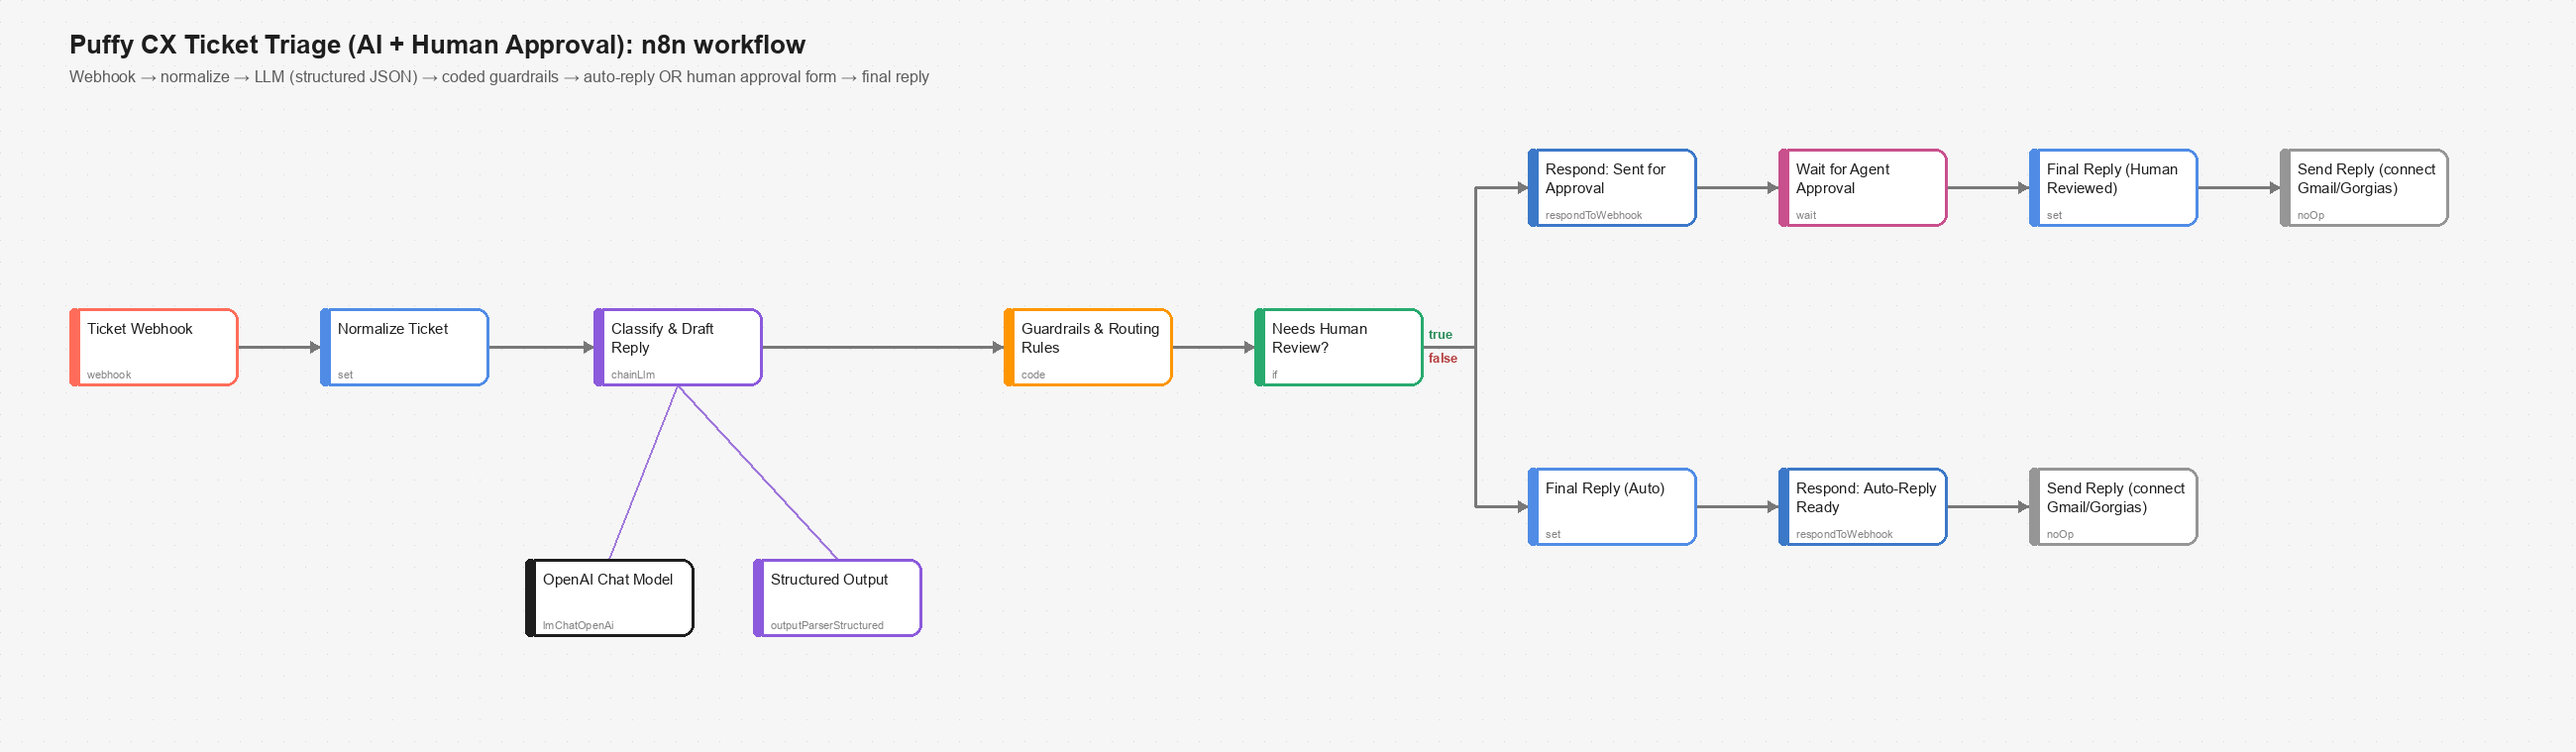
AI ticket triage with human approval (n8n)
LLM drafts · coded guardrails decide · a human approves risky cases
A webhook takes a customer ticket; an LLM classifies it and drafts a reply as structured JSON; deterministic rules route refunds, warranty, low-confidence or high-value cases to an Approve / Edit / Reject form. Tested on 8 scenarios including Arabic and a prompt-injection attempt.
n8nOpenAIStructured outputsHuman-in-the-loop
Open source
small-model-agents
Agent evaluation harness · CI regression gate · MCP server
Public work on making small models reliable agents: an evaluation harness with a CI gate that blocks regressions, plus a published Model Context Protocol server (stdio JSON-RPC).
ReactReact Nativen8nWhatsApp Business APISIP / VoIP
Experience & education
Jun 2022 – present
AI/ML Engineer · Netstratum Technologies, Kochi
Production LLM, speech and document-AI systems for an enterprise on-prem AI platform and its customers: Echo, the agent engine, RAG, vision, and Kubernetes delivery across 8 environments.
2018 – 2022
B.Tech, Computer Science & Engineering
KMEA Engineering College, APJ Abdul Kalam Technological University.
Languages
English (fluent) · Malayalam (native)
Also Hindi and Urdu; proficient in Arabic (reading, comprehension and writing).
Let's build your AI core.
Happy to talk about AI engineering roles, consulting and collaborations.